Why Am I Able to Upload a Csv File to Matlab but Not Another
28. Mai 2018
 How do you analyse Strava activities—such every bit runs or bike rides—with Colab, Python, Pandas, and Matplotlib? In this mail service, I am demonstrating how to get started, and will give you a taster of what is possible with this state-of-the-art technology for data assay.
I am both curious and skeptical. I honey running. And I also happen to like statistics. You lot won't exist suprised if I tell you now that I discover the following questions interesting:
- Do I run longer distances on the weekend than during the calendar week?
- Do I run faster on the weekend than during the week?
- How many days do I residue compared to days I run?
- How many kilometers did I cover during run-commutes?
- Which month of the year practice I run the fastest?
- Which calendar month of the year do I run the longest altitude?
- Which quarter of the yr do I run the fastest?
- Which quarter of the yr practise I run the longest altitude?
- How has the average distance per run changed over the years?
- How has the average time per run changed over the years?
- How has my boilerplate speed per run inverse over the years?
- How much altitude did I run in races and how much during training?
- so on and and then on…
If you're bored by now, that's okay. Maybe you better end reading hither. Even so, should you be curious how to respond these questions past analysing sports activities with Colab, Python, Pandas, and Matplotlib, continue reading.
If you take not heard of Colab, Pandas, Matplotlib before—that's okay! You should still be able to get a picture of what these are capable of.
- Strava: a mobile application that allows you lot to runway athletic activities. See www.strava.com.
- Colab: a Python notebook highly suited for information assay using a "literal-programming" style. See colab.research.google.com.
- Pandas: open-source library providing information structures and data assay tools for Python. See pandas.pydata.org.
- Matplotlib: a second plotting library for Python. See matplotlib.org.
Strava provides various tables and visualizations on its website. But I notice that Strava rarely happens to visualize the data in a way that answers my questions. What to practice?
Outline of steps
The solution I describe here is to export all the activities recorded with Strava to a comma-separated values file (CSV)—runs, bike trips, hiking trips, and ice-skating trips. Then load the activities into Pandas data frames, and utilize these data frames to analyse and plot the activities.
- request all activities from Strava (instructions) as a naught archive
- import activities.csv from the zip archive into Google Sheets (instructions)
- create a new Colab (instructions)
- import information from Google Sheets into Colab (use the snippet "Importing data from Google Sheets")
- use Pandas to transform and process the activities
- use Matplotlib for creating visualizations
I am not going to provide a detailed walkthrough here—you can wait at the Colab.
Download Colab notebook
File: Analysing_Strava_activities_using_Colab,_Pandas_and_Matplotlib_(Part_1).ipynb [6.45 kB]
Category:
Download: 811
You tin open this Colab notebook using Get to File>Upload Notebook… in Colab.
Getting started
In the following, I volition explain some key steps in how to get started with analysing your Strava activities.
It is easy to load information from CSV files, Microsoft Excel spreadsheets, or Google Sheets into a Pandas information frame.
Equally the very showtime step, we tin have out all your data on Strava ( (instructions). In the zip archive, we will find an activities.csv file containing a listing of all your activities. Nosotros can then upload this CSV file to Google Drive and convert it into a Google Sheet. Then we tin insert a snippet into a Colab document, which loads the Google Sail into a Pandas data frame.
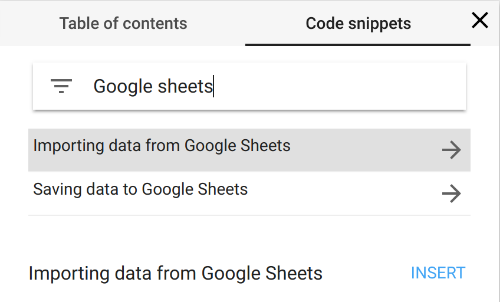
Alternatively, you could probably also adjust the sharing settings of the CSV file in Google Bulldoze to make the file readable by anyone with the link, and then utilize the pandas.read_csv function to import the data from the CSV file. Any works best for yous…
Preparing the data
Assuming that nosotros take loaded a Google Sheet into the variable worksheet, we tin then create a Pandas information frame.
import pandas as pd rows = worksheet.get_all_values() activities_raw = pd.DataFrame.from_records(rows[1:], columns=rows[0]);
The information frame activities_raw holds the unprocessed information from the spreadsheet. At present follows a typical step, and that is transforming the data into a shape that makes it easy to do further data assay. Let us copy the raw data before modifying it simply then that nosotros tin can avoid reloading the data.
#@championship Index activities, convert data types, convert units activities = activities_raw.copy()
Not all of the columns in the exported Strava activities are relevant; we can easily retain but a few columns. In this case, the time at which the activity started, the blazon of the action ("Run", "Hike", "Ride", "IceSkate"), the altitude, the duration, whether the activeness was a commute to piece of work, and the proper noun of the activity.
# Project activities = activities[[ 'date', 'type', 'distance', 'elapsed_time', 'commute', 'proper name' ]]
Let united states of america explicitly convert the columns to the desired information types. This drastically simplifies further processing as we tin can now rely on Pandas doing the right thing when due east.k. summing the values in a column. In this instance, let us choose engagement and type as the (multi-)index.
# Set information types activities['distance'] = activities['distance'].astype(float) activities['elapsed_time'] = activities['elapsed_time'].astype(float) activities['commute'] = activities['commute'].apply(lambda 10: one if x == 'True' else 0)
Permit us now convert the distance from meters to kilometers, and the elapsed time from seconds to minutes—this makes sense for me considering I observe minutes per kilometer intuitive as a measure out of step.
# Catechumen units activities['distance'] = activities['distance'] / yard activities['elapsed_time'] = activities['elapsed_time'] / 60
Finally, and this is a crucial step in Pandas, allow us define the index for the dataframe such that nosotros can easily address each activeness by engagement and blazon. This makes it very easy to group activities by date and/or past blazon. Then nosotros can prove statistics for running only, or compare activity types.
If you are unfamiliar with Pandas information frames, the index of a data frame is somewhat similar to the main fundamental of a tabular array in a relational database—although the alphabetize of a data frame does non accept to be unique.
# Index activities['appointment'] = pd.to_datetime(activities_raw['engagement']) activities.set_index(['date', 'blazon'], inplace= True)
Answering basic questions
Let's await at some of the information.
print( activities[['distance', 'elapsed_time']] .sample(5) .sort_index() .to_string(formatters={ 'distance': '{:.0f}km' .format, 'elapsed_time':' {:.0f}min' .format, }))
This shows v randomly selected rows from the data frame.
altitude elapsed_time date type 2015-02-01 10:06:52 Hike 25km 419min 2015-04-06 ten:58:24 Run 11km 84min 2016-08-31 08:01:32 Ride 5km 22min 2016-x-05 eighteen:02:36 Ride 6km 29min 2017-10-07 08:01:57 Run 78km 1068min
Getting the data into an advisable format is crucial for farther analysis. We are now in a good shape. Permit's accept a look for which blazon of activity I have the virtually recordings, and in which activeness I have covered the virtually distance:
print( activities['distance'] .groupby(level= 'blazon') .agg(['count', 'sum']) .sort_values(by= 'count', ascending= Fake) .to_string(formatters={'sum':' {:.0f}km' .format}))
This prints:
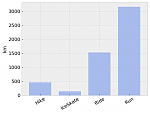
count sum blazon Run 255 3153km Ride 100 1526km Hike 17 465km IceSkate three 146km
Permit us find out over which time menses these activities were recorded:
first_date = activities.index.levels[0].min() last_date = activities.index.levels[0].max() print('Activities recorded from %s to %due south , total of %d days.' % ( first_date.strftime('%Y-%grand- %d '), last_date.strftime('%Y-%chiliad- %d '), (last_date - first_date).days))
This prints:
Activities recorded from 2014-06-23 to 2018-05-26, total of 1433 days.
So almost 4 years of information! We need to be careful, though. The data shows just the activities that were recorded on Strava. I know that I have not ever recorded wheel rides, hikes, and ice-skating trips. In contrast, I have been diligently recording nigh all of my runs over the past years; for running, the least corporeality of data is missing.
What is next
You might rightly enquire. And then why use Colab, Python, Pandas, Matplotlib to perform this basic data assay? We could too just have used Google Sheets or Microsoft Excel to convert betwixt units, compute sums, create pivot tables and so on; this nigh probable would accept been far easier to practice. I am not going to compare betwixt the dissimilar tools for data analysis. In the next articles, I volition expect at the unanswered "research" questions stated to a higher place, and to answer these, we need to perform more complex analysis of the data—hither we volition reap the benefits of our investment to get the activities into the right format. This is where Colab, Pandas, and Matplotlib volition shine. Stay tuned.
Read the next article in this series
Articles in this series:
- Part 1
- Part 2
- Part 3
- Part 4
schmidtnurreacuot.blogspot.com
Source: https://www.athoughtabroad.com/2018/05/28/analysing-strava-activities-using-colab-pandas-matplotlib-part-1

Post a Comment for "Why Am I Able to Upload a Csv File to Matlab but Not Another"